DeepEval
EvaluationApache-2.0
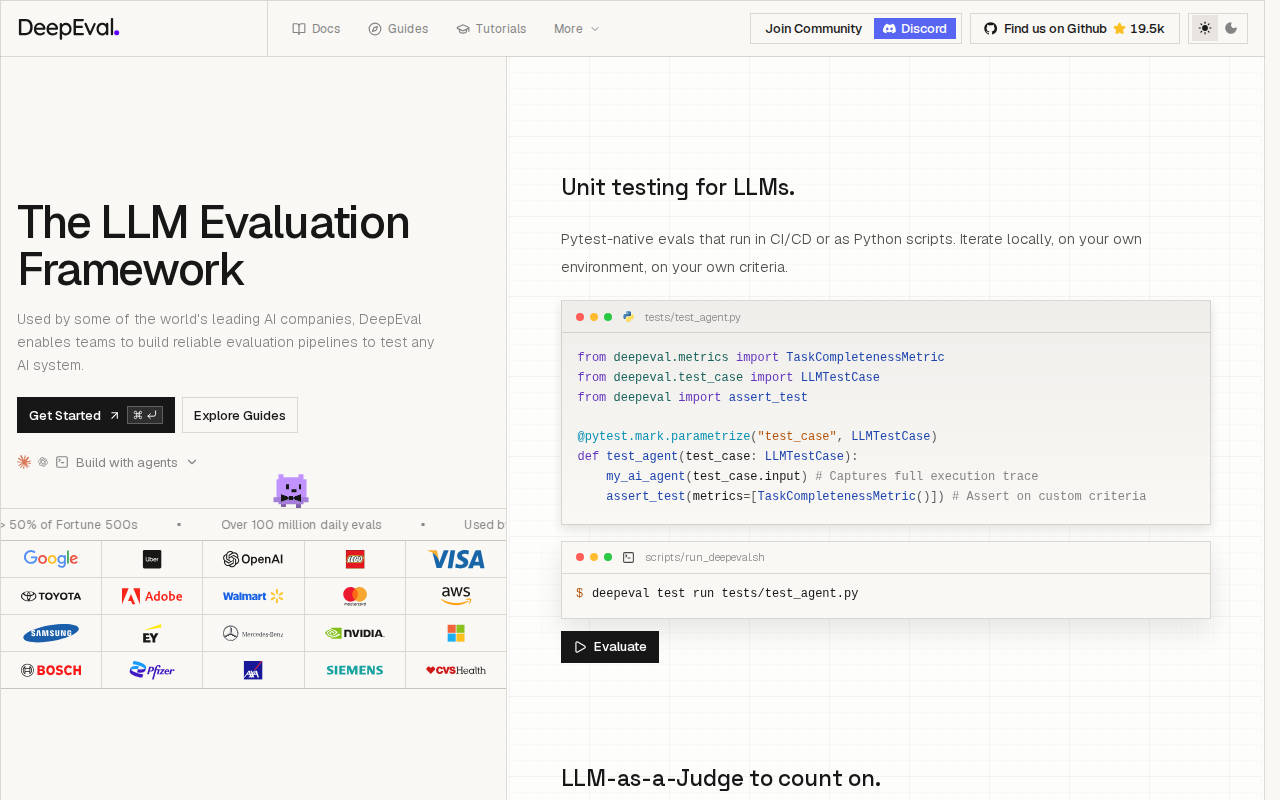
DeepEval is a Python framework that scores LLM outputs and agent runs against test cases, including metrics for tool use and MCP servers. It is made by Confident AI, and test reports can be sent to the Confident AI platform.
The README lists metrics for MCP task completion and MCP use, TypeScript integrations for the Vercel AI SDK and Mastra, and a command line used to run test files and log in to the platform.
Pinout
- MCP server: not checked yet
- HTTP API: not checked yet
- command line: supported, verified
- Python SDK: not checked yet
- TypeScript SDK: supported, verified
- OpenAPI description: not checked yet
| Interface | Status | Source we read | Read on |
|---|---|---|---|
| MCP server | Not checked yet | — | — |
| HTTP API | Not checked yet | — | — |
| Command line | Supported, verified | README, "run test_ai_agent.py in the CLI" | |
| Python SDK | Not checked yet | — | — |
| TypeScript SDK | Supported, verified | Getting started, Installation (npm install --save-dev deepeval) | |
| OpenAPI description | Not checked yet | — | — |
Facts
| License | Apache-2.0. GitHub API, repository license field, read . |
|---|---|
| Main language | Python (as detected by GitHub). GitHub API, repository record, read . |
| Publisher | confident-ai (GitHub organization). GitHub API, repository record, read . |
| Latest GitHub release | python-v4.2.4, published 2026-09-22. GitHub API, latest release, read . |
| MCP metrics | MCP Task Completion, MCP Use, Multi-Turn MCP Use. README in the repository, read . |
| Hosted option | Confident AI platform for shared test reports. README in the repository, read . |
| Last commit | . GitHub API, latest commit on the default branch of confident-ai/deepeval, read . |
Limits
- Cloud test reports need an account and an API key on the Confident AI platform, entered through the command line, as described in the README.
Strengths
- The README documents metrics written for agents that call MCP servers.
Alternatives to DeepEval
All evaluation tools for agents
Open-core platform to trace, test and evaluate agents and coding assistants.
Framework for evaluating, testing and monitoring ML and LLM systems.
Readymade evaluators that score an agent's trajectory of steps.
Observability and evaluation platform for tracing and improving AI agents.
Last check: . Method: public repository and docs read automatically, page and day written down. Next check due within 90 days. How we check
Is this your tool? Write to hello@agent-tools.directory from an address on its domain to correct a pin or a fact.